How to Measure Product-Market Fit With AI Agents
Use a PMF survey to learn who would miss your product, then compare their answers with activation and repeat use in Agent Analytics.
People say they like your product. Would they miss it?
That question gets more useful as agents help you ship more features. You can keep adding things people requested without learning which part of the product they depend on.
A product-market fit survey helps you find that dependence. Your agent can organize the responses and compare them with product behavior. You still need to decide who to ask, what the answers mean, and whether the evidence supports the next investment.
The goal is a clearer picture of who gets lasting value from the product.
TL;DR: copy this to your AI agent
Use this with Claude Code, Codex, Cursor, Hermes, or the agent already working on your product:
Help me prepare a product-market fit survey. Read the product and current Agent Analytics context. Propose an eligibility rule for users who have experienced the core value, a short questionnaire, and a plan for comparing responses with activation and repeat use. State what the survey cannot establish. Prepare the materials for review before contacting anyone.If responses already exist, give the agent the export and ask it to audit the sample before calculating a score.
The Sean Ellis question, without the magic number
The familiar PMF survey asks:
How would you feel if you could no longer use this product?
The response choices are very disappointed, somewhat disappointed, and not disappointed. Rahul Vohra’s account of Superhuman’s PMF process explains how the team used Sean Ellis’s question and his 40% benchmark to investigate demand.
Treat 40% as a reference point. Crossing it does not establish retention, willingness to pay, a viable market, or sustainable economics. The result describes the people who answered under your sampling rules.
For an agent-built product, there is another distinction: successful automated runs do not tell you whether the human customer would miss the service. Ask the person who experiences or depends on the outcome.
Choose respondents before reading their answers
Superhuman surveyed people who had used its core product at least twice in the previous two weeks. That was a concrete eligibility rule for that product, not a universal cadence.
Write your own rule around experienced value. A daily writing tool and a monthly invoicing tool should not use the same recency requirement simply because a template says so.
Suppose you run a tool that helps freelance designers prepare and send client proposals. This is a hypothetical example. You might initially study designers who sent at least two real proposals in the previous month. That is an illustrative eligibility rule, not a measured recommendation.
Decide these details in advance:
| Decision | What to record |
|---|---|
| Unit | One response per person, or one designated respondent per account |
| Experience | The real task they must have completed |
| Recency | The period that fits the product’s expected use |
| Exclusions | Employees, test accounts, duplicates, and other predefined cases |
| Recruitment | Everyone eligible, or a documented selection method |
For a team product, distinguish the daily user from the person who pays. Their answers can both matter, but mixing them without identifying the role makes interpretation harder.
Do not recruit only your friendliest customers. Keep a separate research group for people who tried the product and stopped. An active-user survey can reveal dependence among current users while missing the reasons others left.
The AAPOR survey guidance emphasizes matching the sample to the population you want to understand and being transparent about how participants were selected.
Ask for the value behind the answer
Keep the questionnaire short. After the main question, ask respondents to describe:
- the task the product helps them finish;
- the benefit they would most miss;
- the alternative they would use;
- the biggest obstacle to getting that benefit.
Those are prompts for learning, not a feature wishlist. “Add more templates” becomes more useful when you understand which client situation the existing templates fail to handle.
Use an ordinary form tool or your existing research workflow to collect responses. In this workflow, Agent Analytics supplies behavioral evidence; it does not collect the survey.
Allow people to skip a question or say they cannot judge yet. Keep those answers visible in the report, with a documented rule for whether they belong in the main score.
Test the form with a few suitable people before sending it broadly. Keep the wording, answer choices, order, and invitation approach consistent across waves. Pew Research Center’s questionnaire guidance explains how wording and question order can affect responses and comparisons over time.
Your agent can draft the form. It should not invent responses, answer on customers’ behalf, or turn the invitation into a pitch.
Show the denominator beside the score
Calculate the share of eligible respondents with a valid main-question answer who selected the strongest disappointment response:
very-disappointed responses / valid main-question responsesFor example, 12 of 30 = 40%. These numbers are invented to illustrate the calculation.
Show the counts. In that sample, changing two answers changes the result by about seven percentage points. A neat percentage can look more stable than the evidence behind it.
Keep a simple accounting of the survey:
eligible people -> invited -> responded -> valid main-question answersReport skipped answers, exclusions, and duplicate handling separately. Do not count silence as disappointment or silently drop an inconvenient answer.
Ask your agent:
Audit this survey export against our saved eligibility and duplicate rules. Report the invitation count, response count, valid-answer denominator, all answer categories, and exclusions. Calculate the score from counts. Flag small groups and possible response bias. Do not label any threshold as proof of product-market fit.More responses help with instability, but they do not automatically fix selection bias. People who choose to answer may differ from those who ignore the survey. An uncertainty interval based on a statistical model does not correct that difference by itself. AAPOR’s guide to sampling error and credibility intervals explains why opt-in samples require particular care.
Let the agent organize the language, then inspect it
The useful question is what people would miss and why.
Give your agent the response export with names, emails, and unnecessary personal details removed. Preserve a private response ID so you can trace a theme back to its source.
Ask it to group answers into a small set of benefits, situations, alternatives, and obstacles. Require response IDs and short supporting excerpts. Keep contradictory answers and an “unclear” category instead of forcing every sentence into a tidy story.
Group the open-text answers by the benefit people value and the obstacle they describe. For each theme, show the number of distinct respondents, response IDs, supporting excerpts, and counterexamples. Separate explicit statements from your interpretation. Mark ambiguous answers for my review.Read the underlying answers before accepting the labels. Count people rather than mentions so one long response does not become five votes. If a response belongs to several themes, say that the theme totals overlap.
You may discover a promising subgroup. Keep the full-sample result visible alongside it, report the subgroup’s size, and label a segment discovered after reading the answers as exploratory. Confirm it with another cohort before treating it as your whole market.
Bring activation and repeat use into the review
The survey tells you what respondents say they value. Product events help you examine what they actually do.
Connect through the AA guide for your agent environment. If it supports skills and command execution, install:
npx skills add agent-analytics/skillsChoose agent-analytics if prompted. Follow the skill setup guide and ask:
Use the Agent Analytics skill to verify the project for this product. Read existing goals, activation events, and event meanings. Inspect the code and real event names. Help me confirm which completed task represents value, then check that the event arrives with a stable user identity. Preserve existing context when updating it.For the hypothetical proposal tool, proposal_sent could represent a real proposal successfully sent to a client. It should fire at that application outcome, not when someone clicks Send or opens a sample. These are example event names; reuse your product’s existing vocabulary.
The tracker reference documents custom events and stable user identification. Have the agent verify that browser activity and server outcomes use the intended identity before interpreting them as one journey.
Use a funnel to inspect whether new users reach the value event. Use event-based retention to examine whether they repeat it. A return visit alone can mean someone checked a setting and left.
For a shell-capable agent, the current CLI supports this example:
npx --yes @agent-analytics/cli@0.5.37 retention proposal-tool \
  --period week --cohorts 8 \
  --event proposal_sent --returning-event proposal_sent
Replace the project and event names. The retention API contract supports an entry event and a returning event. This command groups users by their first matching event within its lookback window and checks subsequent weekly activity. Those users may have used the product earlier. It is a product-wide view, not a retention report filtered to survey respondents.
Choose periods that fit the task and compare cohorts at the same age. A new cohort has not had the same opportunity to return as an older one. Funnels and retention require paid access under the current CLI documentation.
Keep the survey join explicit
If you need to compare respondents’ answers with their own behavior, plan the link before collection. Explain that use to participants. Keep the response-to-user mapping in your private research workspace; use stable application IDs, not guessed matches from names.
AA’s API reference provides identity-based event and journey reads. Your agent can use supported reads to inspect linked users, then combine that evidence with the survey export locally. Check date coverage, pagination, and query limits before claiming the result includes everyone.
Do not ask the agent to invent a survey-cohort filter on the retention command. If the available reads cannot support the exact comparison, keep the survey and product-wide retention findings separate. Anonymous surveys can still be useful, but they cannot support a person-level behavioral join without a reliable link.
Keep raw responses and temporary survey scores out of AA project context. Store durable event meanings there; keep the research report in your normal files.
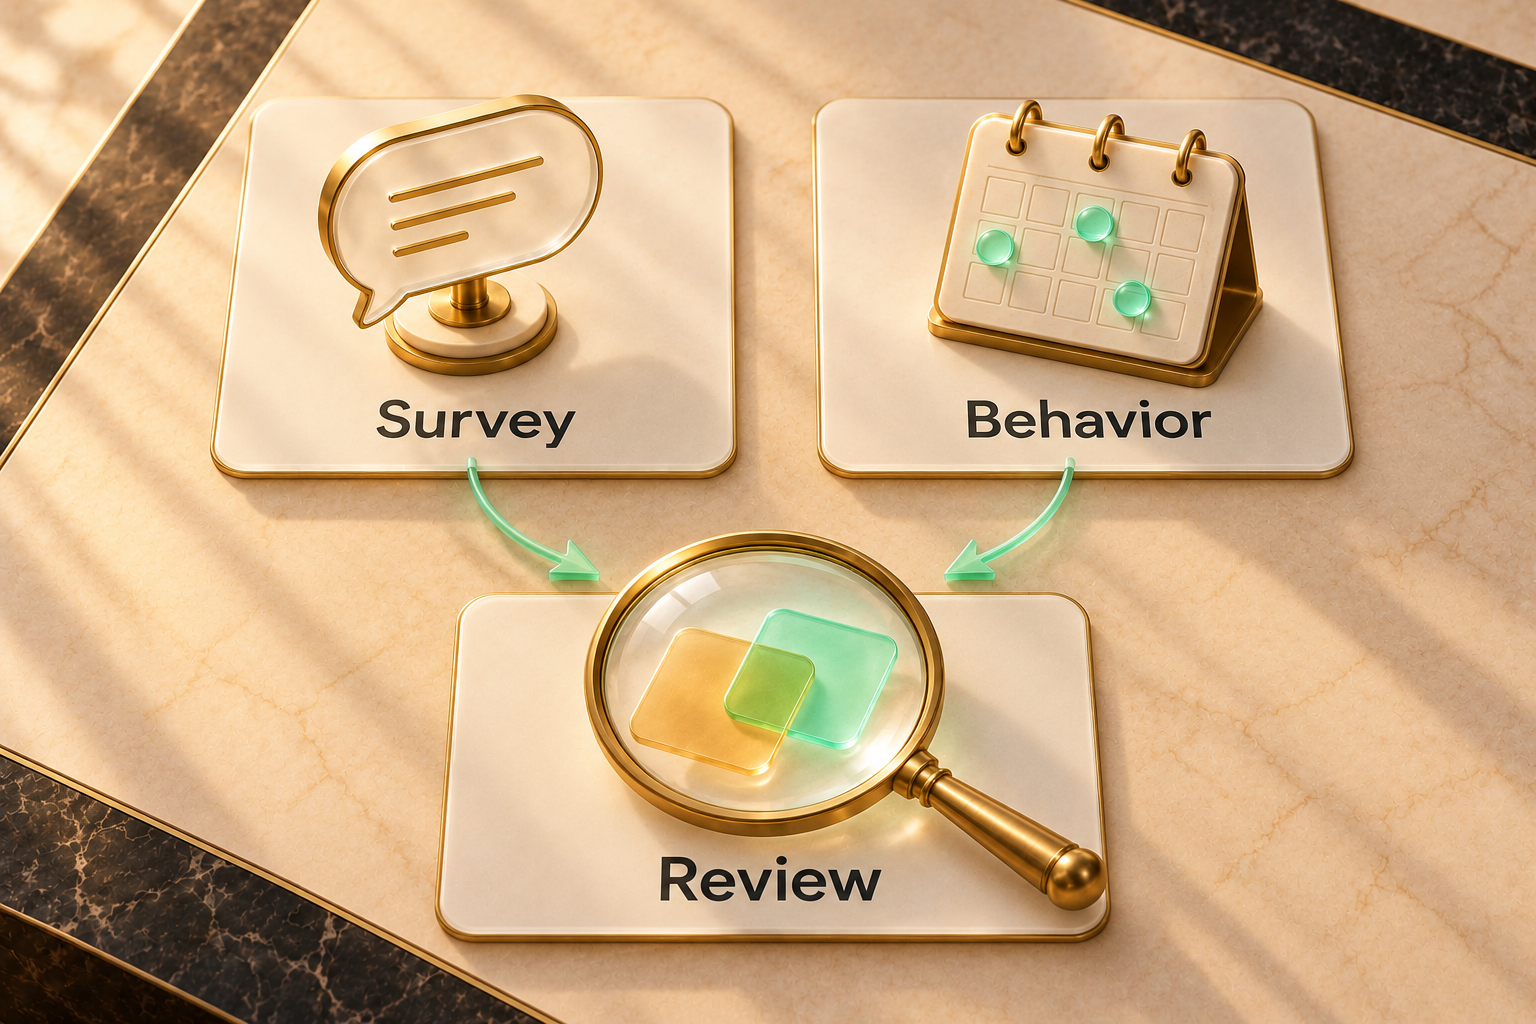
Investigate disagreement before adding features
For the proposal tool, the useful findings might look like this. These are hypothetical interpretations, not results:
| Pattern | Next question |
|---|---|
| Strong stated dependence, repeated real use | Which benefit and customer situation explain both? |
| Strong stated dependence, little repeat use | Is the task infrequent, tracking incomplete, or the answer disconnected from behavior? |
| Weak stated dependence, repeated use | Is this convenient but replaceable? What would make switching easy? |
| Few users reach value at all | What can onboarding research explain that an active-user survey misses? |
Check renewals, purchases, or other commercial evidence in the systems that actually record them. A well-liked free tool and a sustainable business are different questions.
Choose one follow-up from the evidence: investigate an obstacle, interview a promising segment, repair an event, or collect another wave. Changing the audience can move the score even when the product is unchanged, so preserve the sampling rules and explain any changes.
Ask for a research brief, not a PMF verdict
At the next review, give your agent this prompt:
Prepare our PMF research brief. State who was eligible, who answered, the counts behind the score, and the main benefits and obstacles with response evidence. Compare activation and repeat use where the data supports it. Separate respondent-level findings from product-wide context. Show contradictions, missing data, and one recommended follow-up. Do not declare PMF from the survey threshold.STP helps choose a market. Jobs To Be Done helps describe the progress people want. A PMF survey adds a different piece: who already depends on what you have built, and what they would miss.
Give your agent the job of making that evidence easier to inspect. Keep the decision tied to the people behind the percentage.